How Strategic Data Collection Builds Stronger AI Systems
Artificial intelligence systems depend on data long before model training begins.
Before information can be annotated, evaluated, or used to improve machine learning performance, it must first be collected in a way that reflects the real environment in which the AI system will operate.
This makes data collection one of the most important stages in the AI development lifecycle.
A dataset can be large and still be ineffective if it lacks diversity, relevance, structure, or consistency. On the other hand, carefully planned data collection can provide AI teams with the foundation they need to build systems that perform more reliably across different users, languages, markets, and real-world conditions.
For this reason, successful AI data projects should not begin with the question:
How much data can we collect?
They should begin with:
What data does the model actually need to learn from?
What Is AI Data Collection?
AI data collection is the process of gathering information that can be used to train, test, or evaluate artificial intelligence and machine learning systems.
Depending on the project, this data may include:
- Text
- Images
- Audio
- Speech
- Video
- Documents
- User interactions
- Search queries
- Product information
- Environmental data
- Multilingual content
The type of data required depends on the AI application.
A speech recognition system needs voice recordings.
A computer vision model requires images or video.
A conversational AI system may need user queries, responses, dialogue examples, and intent data.
A multilingual model may require text and speech from different languages, regions, and cultural contexts.
The collection strategy should therefore be designed around the model’s intended use.
Why Data Collection Quality Matters
Machine learning models learn patterns from the examples they receive.
If the collected data is incomplete, repetitive, unbalanced, or irrelevant, the model may learn patterns that do not reflect real-world usage.
Consider a computer vision system designed to recognize vehicles.
If the training dataset contains mostly vehicles photographed during daylight, the model may struggle when exposed to night-time images.
Similarly, a speech model trained primarily on one accent may perform less effectively when users speak with different accents or dialects.
The quality of AI data collection is therefore closely connected to the diversity and relevance of the final dataset.
Data Collection Should Begin With Clear Objectives
Before contributors begin collecting information, the project should define exactly what the dataset is intended to support.
Important questions may include:
- What AI system will use the data?
- What data types are required?
- Which languages or markets are included?
- Who are the expected users?
- What environments should the data represent?
- What technical specifications are required?
- What metadata should accompany each item?
- How will the dataset be evaluated?
Answering these questions helps prevent unnecessary collection.
It also helps teams focus on data that provides meaningful value to the model.
Different AI Applications Need Different Data
There is no universal dataset that works for every AI system.
Each application requires its own data strategy.
Natural Language Processing
NLP projects may require:
- Sentences
- Conversations
- Search queries
- Reviews
- Questions and answers
- Domain-specific terminology
- Multilingual text
The dataset may need to represent different writing styles, topics, and user intents.
Computer Vision
Computer vision projects may require:
- Product images
- Street scenes
- Documents
- Faces
- Objects
- Indoor environments
- Outdoor environments
- Video footage
Collection conditions such as lighting, camera angle, distance, and background can affect the usefulness of the data.
Speech AI
Speech projects may require:
- Voice commands
- Conversations
- Read speech
- Spontaneous speech
- Regional accents
- Multiple devices
- Different recording environments
Generative AI
Generative AI projects can involve many forms of data, including:
- Prompts
- Responses
- Instruction-following examples
- Preference data
- Evaluation tasks
- Multilingual examples
The collection methodology should match the intended AI behavior.
The Importance of Data Diversity
One of the biggest challenges in AI data collection is ensuring that the dataset represents the variety of users and situations the model will encounter.
Diversity can involve many dimensions.
For speech data, this may include different accents, ages, speaking speeds, and recording environments.
For image data, diversity can include lighting, geography, object position, camera quality, and background conditions.
For multilingual text, diversity may involve regional vocabulary, writing style, dialect, and cultural context.
The goal is not simply to collect many different examples.
The goal is to collect meaningful variation.
Multilingual Data Collection
AI products increasingly operate across multiple markets.
This makes multilingual data collection especially important.
Language data should reflect how people naturally communicate in each target market.
A multilingual project may require contributors from different regions to generate or collect:
- Search queries
- Spoken commands
- Conversational phrases
- Product descriptions
- User questions
- Informal expressions
- Local terminology
Native-language data can provide patterns that may not appear in translated datasets.
This is particularly useful for AI systems expected to communicate naturally with users in different regions.
Human Contributors and Data Collection
Many AI data collection projects rely on human contributors.
Contributors may be asked to:
- Record speech
- Capture images
- Write text
- Create prompts
- Submit videos
- Validate collected information
- Participate in conversational tasks
Human contributors allow projects to collect data that reflects real behavior.
However, contributor management becomes an important part of the process.
Clear instructions, qualification criteria, task monitoring, and quality checks help ensure that collected data meets project requirements.
Clear Instructions Reduce Data Errors
Poor instructions can create inconsistent datasets.
For example, an image collection project may require photos taken from specific angles.
If contributors are not given clear examples, they may interpret the task differently.
The same applies to speech recording.
Contributors may need guidance on:
- Speaking speed
- Background noise
- Device type
- Microphone distance
- Prompt reading
- File format
Detailed project guidelines help contributors understand expectations before data collection begins.
Metadata Adds Context to AI Data
The value of collected data often increases when it includes useful metadata.
Metadata describes information about each data item.
For example, a speech recording may include:
- Language
- Dialect
- Recording device
- Speaker category
- Audio length
- Recording environment
An image may include:
- Capture location
- Lighting condition
- Device type
- Object category
- Orientation
Metadata allows AI teams to organize datasets more effectively.
It can also support targeted model evaluation later.
Collecting Text Data for AI
Text data is used in many AI applications.
Projects may collect:
- User queries
- Product reviews
- Documents
- Conversations
- Emails
- Support requests
- Search phrases
- Commands
For multilingual projects, contributors can generate text directly in their native language.
This can help capture natural expressions that may be missing from translated material.
Text collection projects may also require specific topics, intents, or industries.
For example, an AI system designed for customer service may require queries related to orders, payments, returns, and product information.
Image Data Collection
Images are essential for computer vision models.
A good image collection project considers more than the object being photographed.
Useful variation may include:
- Different angles
- Different distances
- Indoor and outdoor environments
- Lighting conditions
- Background complexity
- Camera devices
- Object positioning
A model trained on highly controlled images may struggle when exposed to real-world conditions.
Collecting varied visual data helps reduce this gap.
Video Data Collection
Video introduces additional complexity because it captures movement over time.
Video data may be useful for:
- Activity recognition
- Object tracking
- Autonomous systems
- Gesture recognition
- Retail analytics
- Sports analysis
Collection guidelines may specify camera movement, duration, resolution, frame rate, and scene requirements.
Large video files also require careful organization and storage.
Speech and Audio Collection
Voice AI depends heavily on the quality of recorded speech.
Audio collection projects may require contributors to:
- Read prompts
- Answer questions
- Record spontaneous speech
- Participate in conversations
- Speak specific commands
Recording conditions should reflect the intended application.
For example, a voice assistant used on smartphones may need recordings from different mobile devices.
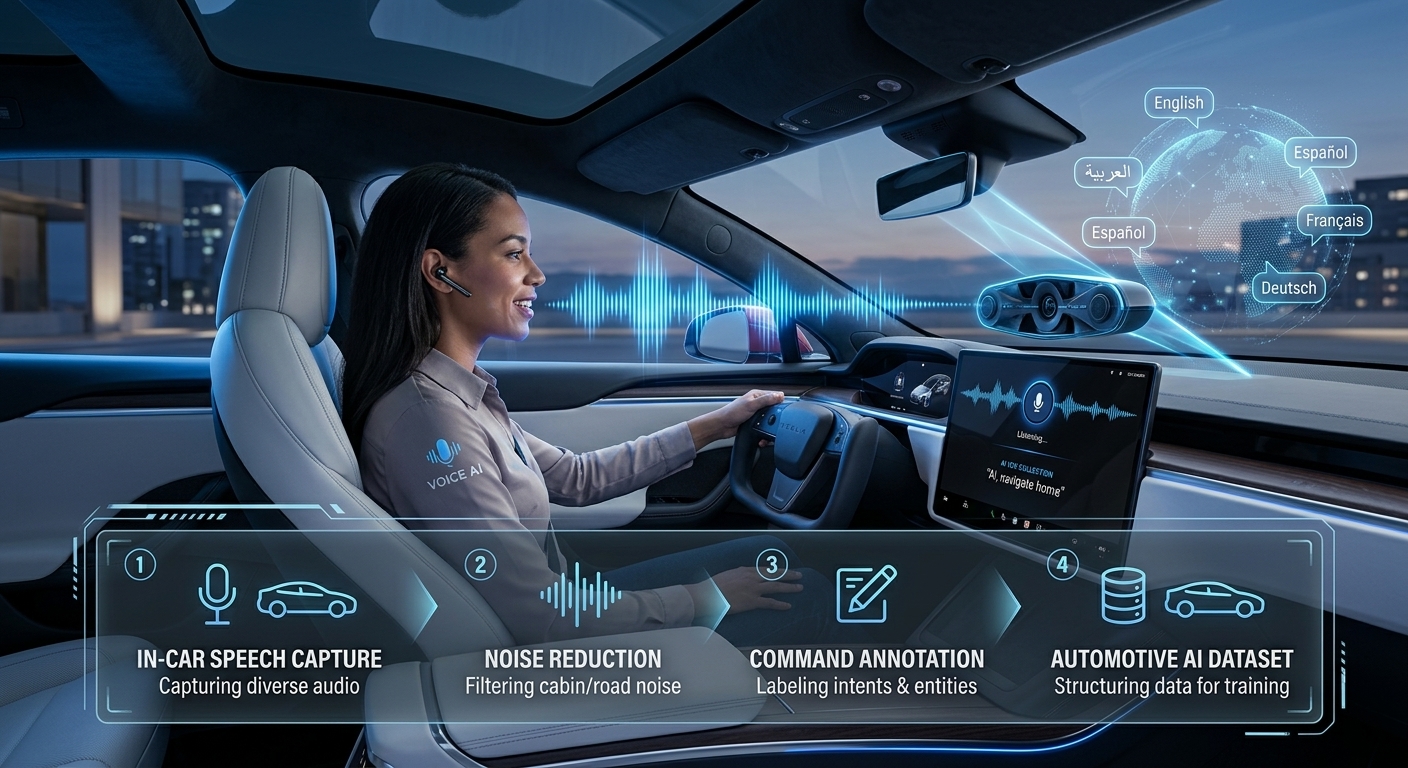
A system designed for vehicles may need speech captured with road noise in the background.
Real-World Data vs. Controlled Data
Some AI projects require carefully controlled data.
Others benefit from realistic variation.
Controlled data makes it easier to standardize collection.
Real-world data helps represent the environment in which the AI system will operate.
Many projects benefit from a combination of both.
For example, a speech dataset might include studio-quality recordings as well as recordings captured in homes, offices, or public spaces.
The appropriate balance depends on the AI use case.
Data Collection at Scale
Large AI projects may require thousands or millions of data items.
Scaling collection involves more than increasing the number of contributors.
Project teams need systems for:
- Task distribution
- Contributor tracking
- File management
- Data validation
- Quality monitoring
- Progress reporting
Without structured management, large collections can become difficult to control.
Clear workflows help maintain consistency as project size increases.
Quality Checks During Collection
Quality assurance should begin while data is being collected.
Waiting until the end of a project can result in large volumes of unusable data.
Early quality checks can identify problems such as:
- Incorrect file formats
- Poor audio quality
- Missing metadata
- Duplicate content
- Incorrect image orientation
- Incomplete tasks
When issues are detected early, project guidelines can be updated before more data is collected.
Data Validation Before Annotation
Collected data often needs to be reviewed before annotation begins.
Validation may involve checking whether the data meets project requirements.
For example:
- Is the image clear?
- Does the recording match the prompt?
- Is the language correct?
- Is the file complete?
- Is the content relevant?
- Is required metadata present?
Only validated data should move into later processing stages.
This helps prevent low-quality inputs from creating problems further down the workflow.
A Typical AI Data Collection Workflow
A structured data collection process might look like:
Project Definition → Contributor Selection → Task Distribution → Data Collection → Validation → Quality Review → Dataset Preparation
Each stage helps ensure that the final dataset meets technical and operational requirements.
Avoiding Dataset Imbalance
A dataset may contain large amounts of data while still being unbalanced.
For example, one category may contain significantly more examples than another.
A speech dataset may include too many speakers from one region.
An image dataset may include too many daytime scenes and not enough night-time scenes.
Monitoring dataset composition during collection helps teams identify these imbalances.
The project can then adjust collection targets before the dataset is finalized.
Ethical and Responsible Data Collection
AI data projects should consider privacy, consent, and responsible data handling.
Data collection practices should follow applicable project requirements and permissions.
This is especially important when working with:
- Personal information
- Voice recordings
- Images of people
- User-generated content
- Sensitive domains
Responsible data practices help protect contributors and improve trust in AI development processes.
Preparing Data for the Next Stage
Collection is usually only the beginning.
After data has been gathered, it may need:
- Cleaning
- Formatting
- Annotation
- Transcription
- Translation
- Validation
- Quality assurance
Well-structured data collection makes these later stages easier.
When files are properly organized and metadata is consistent, annotation teams can work more efficiently.
How Gigverse Solutions Supports Data Collection Projects
Gigverse Solutions supports AI data collection across multiple formats, languages, and markets.
Projects can be designed around specific data requirements, contributor profiles, languages, technical specifications, and target use cases.
Depending on the project, collection workflows can include text, image, audio, speech, video, and multilingual data.
Structured validation and quality review can then help prepare collected data for annotation, model training, testing, or evaluation.
The Right Data Creates a Stronger AI Foundation
AI systems are only as useful as the data they learn from.
Collecting large amounts of information is not enough.
The data should be relevant, diverse, structured, and representative of real users and environments.
A well-designed data collection strategy helps AI teams reduce problems later in the development process.
It provides a stronger foundation for annotation, training, testing, and evaluation.
Before building a better AI model, teams must first build a better dataset.
And that dataset begins with thoughtful data collection.