Artificial intelligence systems depend on data at every stage of development. Whether the goal is to build a computer vision model, improve a natural language processing system, or train an application to understand customer behavior, the quality of the training data has a direct impact on the quality of the final model.
Raw data alone is rarely enough. Images, text, audio, and video need to be organized, labeled, classified, and reviewed before they can become useful training material. This is where data annotation becomes a critical part of the AI development process.
High-quality annotation helps AI systems understand patterns, identify objects, recognize meaning, and make more accurate predictions. Poor annotation, on the other hand, can introduce inconsistencies that affect model accuracy, increase retraining costs, and make it difficult for development teams to understand why a model is underperforming.
At Gigverse Solutions, data annotation is approached as more than a simple labeling task. Effective annotation requires clear project guidelines, trained contributors, structured workflows, and consistent quality assurance.
What Is Data Annotation?
Data annotation is the process of adding meaningful labels or metadata to raw datasets so that machine learning models can understand what the data represents.
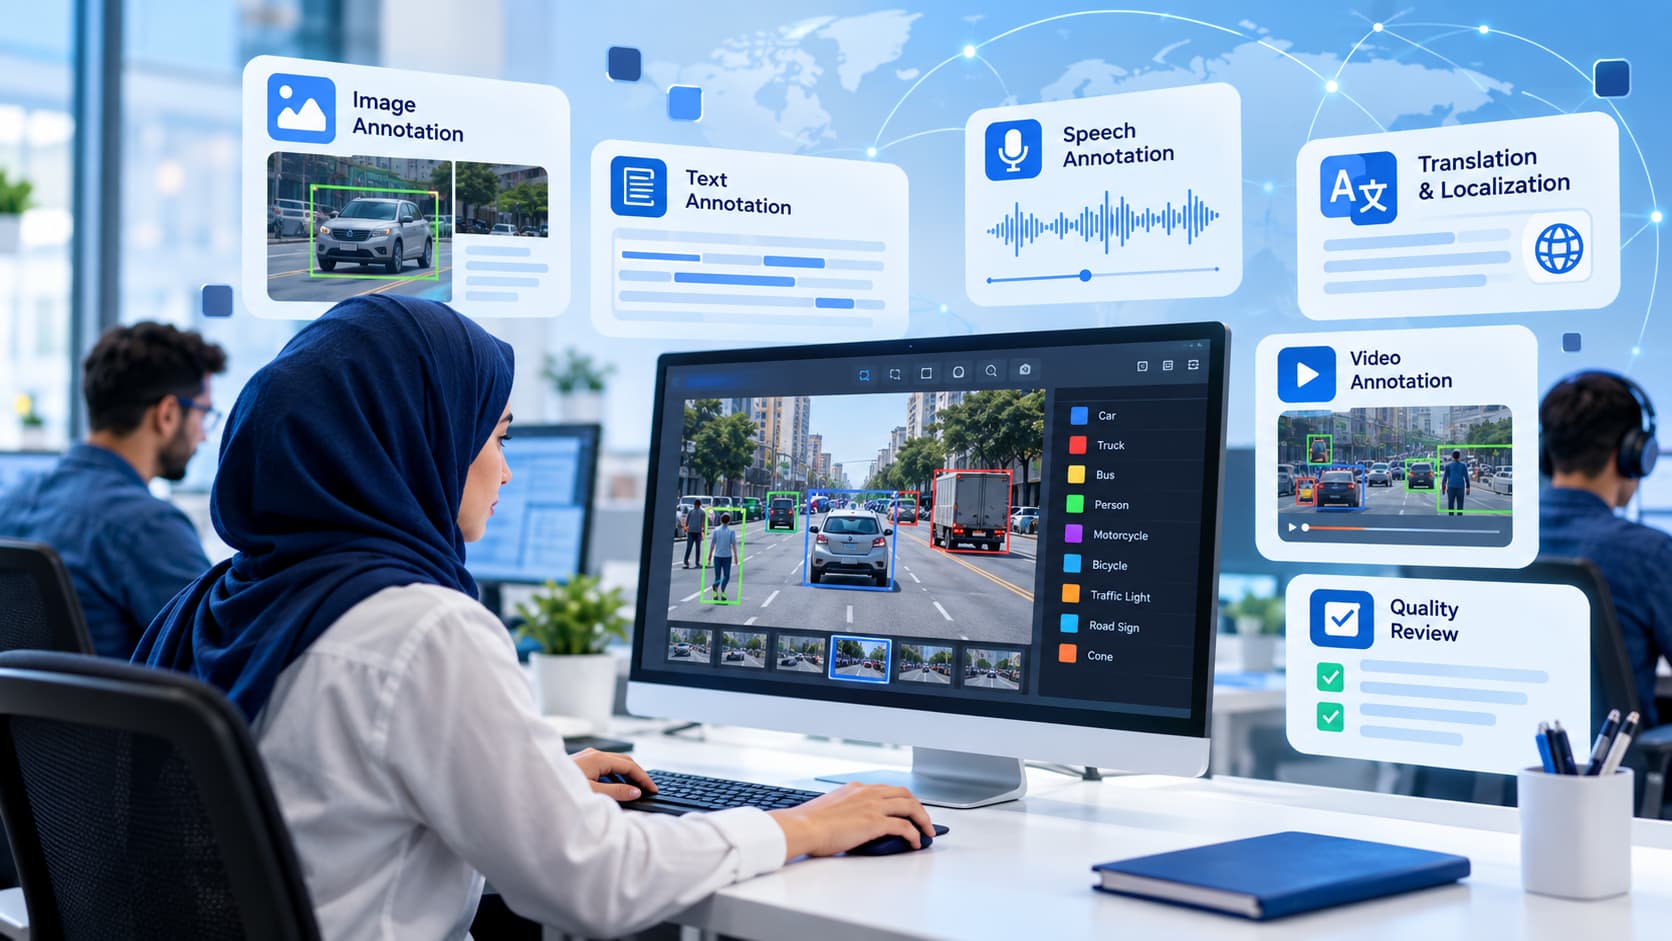
For example, an image may contain a vehicle, pedestrian, road sign, and traffic light. A computer vision model cannot automatically understand each of these elements during initial training. Annotators identify the objects and assign the correct labels so that the model can learn the visual patterns associated with each category.
The same principle applies to other forms of data.
Text can be labeled according to sentiment, intent, topic, entities, or other linguistic characteristics. Audio can be segmented, transcribed, classified, or reviewed for speaker characteristics. Video can be annotated frame by frame to help models recognize movement, objects, events, or behaviors.
The annotation process transforms unstructured information into structured training data that AI systems can use.
Why Annotation Quality Matters
Machine learning models learn from examples. If those examples are inaccurate, inconsistent, or incorrectly labeled, the model may also learn incorrect patterns.
Imagine a dataset used to train an object detection system. If some vehicles are labeled as cars while similar vehicles are labeled as trucks without clear guidelines, the model receives inconsistent information.
These inconsistencies may seem small at the dataset level, but they can create significant problems when thousands or millions of data points are involved.
High-quality annotation creates a consistent relationship between the input data and the expected model output.
This improves the ability of the model to recognize patterns and generalize those patterns when it receives new information.
Clear Guidelines Create Better Datasets
One of the most important steps in any annotation project happens before annotation begins.
The project must define exactly how each data point should be labeled.
Detailed annotation guidelines help contributors understand what categories exist, how to handle unusual cases, how to identify ambiguous data, and when an item should be escalated for review.
Without clear guidelines, different annotators may interpret the same data differently.
For example, consider a sentiment analysis project involving customer reviews. A sentence may contain both positive and negative language. If the project does not clearly explain how mixed sentiment should be classified, contributors may produce inconsistent labels.
Strong annotation guidelines reduce this uncertainty and help ensure that contributors make decisions using the same criteria.
Human Expertise Remains Essential
Automation can support many stages of data processing, but human judgment remains essential in projects where context, language, culture, or ambiguity affects the correct label.
Consider multilingual text annotation.
A sentence may have different meanings depending on local expressions, cultural references, or regional language usage. Literal interpretation may not always represent the actual intention of the speaker.
Human contributors who understand the language and market can interpret the content in context.
This is especially important for projects involving conversational AI, multilingual search, sentiment analysis, translation systems, speech recognition, and generative AI.
Human expertise helps transform raw data into datasets that reflect how people actually communicate and interact.
Quality Assurance Should Be Part of the Workflow
Annotation quality should not be checked only at the end of a project.
A stronger approach integrates quality control throughout the annotation workflow.
Initial samples can be reviewed before full production begins. Contributor performance can be monitored during the project. Difficult or ambiguous tasks can be escalated for additional review. Completed datasets can then go through validation before final delivery.
This layered approach helps identify problems early.
If an annotation guideline is unclear, it can be corrected before thousands of additional items are labeled incorrectly.
If contributors interpret a category differently, the issue can be addressed before it affects the entire dataset.
Continuous quality review can therefore reduce rework while improving dataset consistency.
Different Data Types Require Different Annotation Strategies
Data annotation is not a single standardized process.
The workflow depends heavily on the type of data being processed and the objective of the AI model.
Image annotation may involve bounding boxes, polygons, segmentation, object classification, or keypoint identification.
Text annotation may involve entity recognition, sentiment labeling, intent classification, topic categorization, or content moderation.
Audio projects may require transcription, speaker identification, timestamping, segmentation, or acoustic classification.
Video projects can combine several annotation techniques because objects must often be tracked across multiple frames.
Each project therefore requires a workflow designed around the specific training objective.
Scaling Annotation Without Losing Consistency
AI projects can quickly grow from a small pilot dataset into a large-scale production workflow.
Scaling annotation presents several challenges.
More contributors may be required. Data volumes increase. Multiple languages or markets may be introduced. Quality standards must remain consistent even as the project becomes more complex.
The solution is not simply to add more people.
Scalable annotation requires structured task distribution, contributor qualification, centralized guidelines, quality monitoring, and standardized delivery formats.
Project managers must also track progress and identify bottlenecks before they affect delivery schedules.
When these processes are properly designed, annotation programs can grow while maintaining consistency.
The Role of Multilingual Annotation
Many modern AI systems are designed for global users.
However, language data can vary significantly between regions.
Vocabulary, grammar, dialects, cultural references, writing styles, and conversational patterns may differ even within the same language.
Multilingual annotation helps models understand these variations.
Instead of treating language as a simple translation problem, multilingual projects often require contributors who understand both the language and the cultural context.
This can be particularly important for virtual assistants, customer support systems, search engines, recommendation systems, content moderation tools, and generative AI applications.
A model trained on diverse and accurately annotated language data is better prepared to operate across different markets.
Preparing Data for AI Training
Annotation is usually part of a larger data preparation process.
Before annotation begins, datasets may need to be collected, cleaned, organized, and filtered.
After annotation, datasets may require additional validation, formatting, and quality review.
The complete workflow can involve several stages:
Data Collection → Data Preparation → Annotation → Validation → Quality Review → Structured Delivery
Each stage contributes to the reliability of the final training dataset.
A strong annotation program therefore considers the entire data lifecycle rather than treating labeling as an isolated activity.
Reducing Bias Through Better Data Practices
Dataset diversity is another important consideration.
If an AI model is trained using data that represents only a limited range of users, languages, environments, or situations, its performance may be less reliable when used in broader real-world scenarios.
Annotation workflows can help identify gaps in datasets and ensure that different types of data are represented consistently.
For multilingual or global AI projects, contributor diversity can also help improve contextual understanding.
While annotation alone cannot eliminate every form of bias, structured data practices can help teams better understand and manage the composition of their datasets.
From Raw Data to AI-Ready Datasets
The goal of annotation is not simply to create labels.
The goal is to produce reliable training data that helps AI systems learn effectively.
That requires coordination between project requirements, contributor expertise, annotation guidelines, quality control, and final dataset delivery.
When these elements work together, organizations can create datasets that are easier to train with, easier to evaluate, and easier to scale.
High-quality annotation can also reduce the amount of time development teams spend correcting data problems later in the AI lifecycle.
How Gigverse Solutions Supports Data Annotation Projects
Gigverse Solutions supports AI data projects involving multiple data formats, languages, and annotation requirements.
Depending on the project, workflows can include text labeling, image annotation, audio processing, transcription, classification, validation, and quality review.
Projects can be structured around specific requirements, including data type, language, target market, annotation guidelines, and delivery format.
By combining human contributors with structured workflows and quality assurance processes, Gigverse Solutions helps transform raw information into organized datasets suitable for AI development and evaluation.
Building Better AI Starts With Better Data
AI models may become more advanced, but their performance still depends heavily on the information used to train them.
Accurate annotation gives machine learning systems the structured examples they need to recognize patterns and make better decisions.
For organizations developing AI products, investing in high-quality annotation is therefore not simply a data preparation task.
It is part of building a reliable AI system.
From multilingual text and speech to images and video, carefully designed annotation workflows can help development teams create training datasets that are more consistent, scalable, and useful throughout the AI lifecycle.